Learning Cross-Scale Visual Representations for Real-Time Image Geo-Localization
Tianyi Zhang · Matthew Johnson-Roberson
TL;DR
A self-supervised method locates camera images on small-scale multi-modal maps in real time, correcting drift for robots in GPS-denied environments.
BRIEF
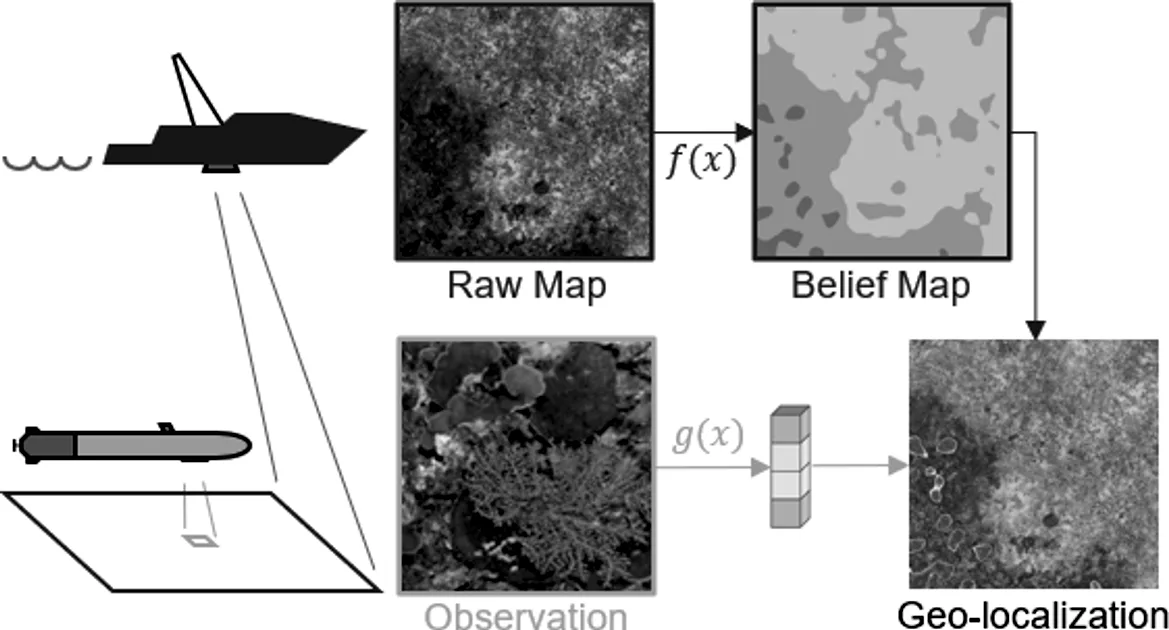
Robots that work without GPS, such as underwater vehicles, drift over long missions when they rely only on cameras or inertial sensors. This work places a camera image onto a 2D geospatial map, such as an aerial or sonar-derived map, to correct that drift. A framework learns visual representations that link images and maps at different scales, without supervision. It is tested on underwater and aerial data, works better on small-scale maps, runs efficiently enough for real-time use, and can feed into existing state estimation pipelines.
Abstract
Robot localization remains a challenging task in GPS denied environments. State estimation approaches based on local sensors, e.g. cameras or IMUs, are drifting-prone for long-range missions as error accumulates. In this study, we aim to address this problem by localizing image observations in a 2D multi-modal geospatial map. We introduce the cross-scale1dataset and a methodology to produce additional data from cross-modality sources. We propose a framework that learns cross-scale visual representations without supervision. Experiments are conducted on data from two different domains, underwater and aerial. In contrast to existing studies in cross-view image geo-localization, our approach a) performs better on smaller-scale multi-modal maps; b) is more computationally efficient for real-time applications; c) can serve directly in concert with state estimation pipelines.2